DeepEvidence
Nature Machine Intelligence 2026
A multi-agent deep research system that searches biomedical knowledge bases and literature and builds an evidence graph to support transparent evidence synthesis.
Making Large Language Models Reliable Data Science Programming Copilots for Biomedical Research
This study measures how reliably large language models write data analysis code for biomedical research, finds overall accuracy below 40% on a new benchmark of 293 tasks, and shows that planning the analysis before coding raises it to 74%.
Large language models can turn a plain request into analysis code and a plot in seconds. In biomedical research, though, a plausible-looking but wrong analysis can spread incorrect findings. How often is the code actually right?
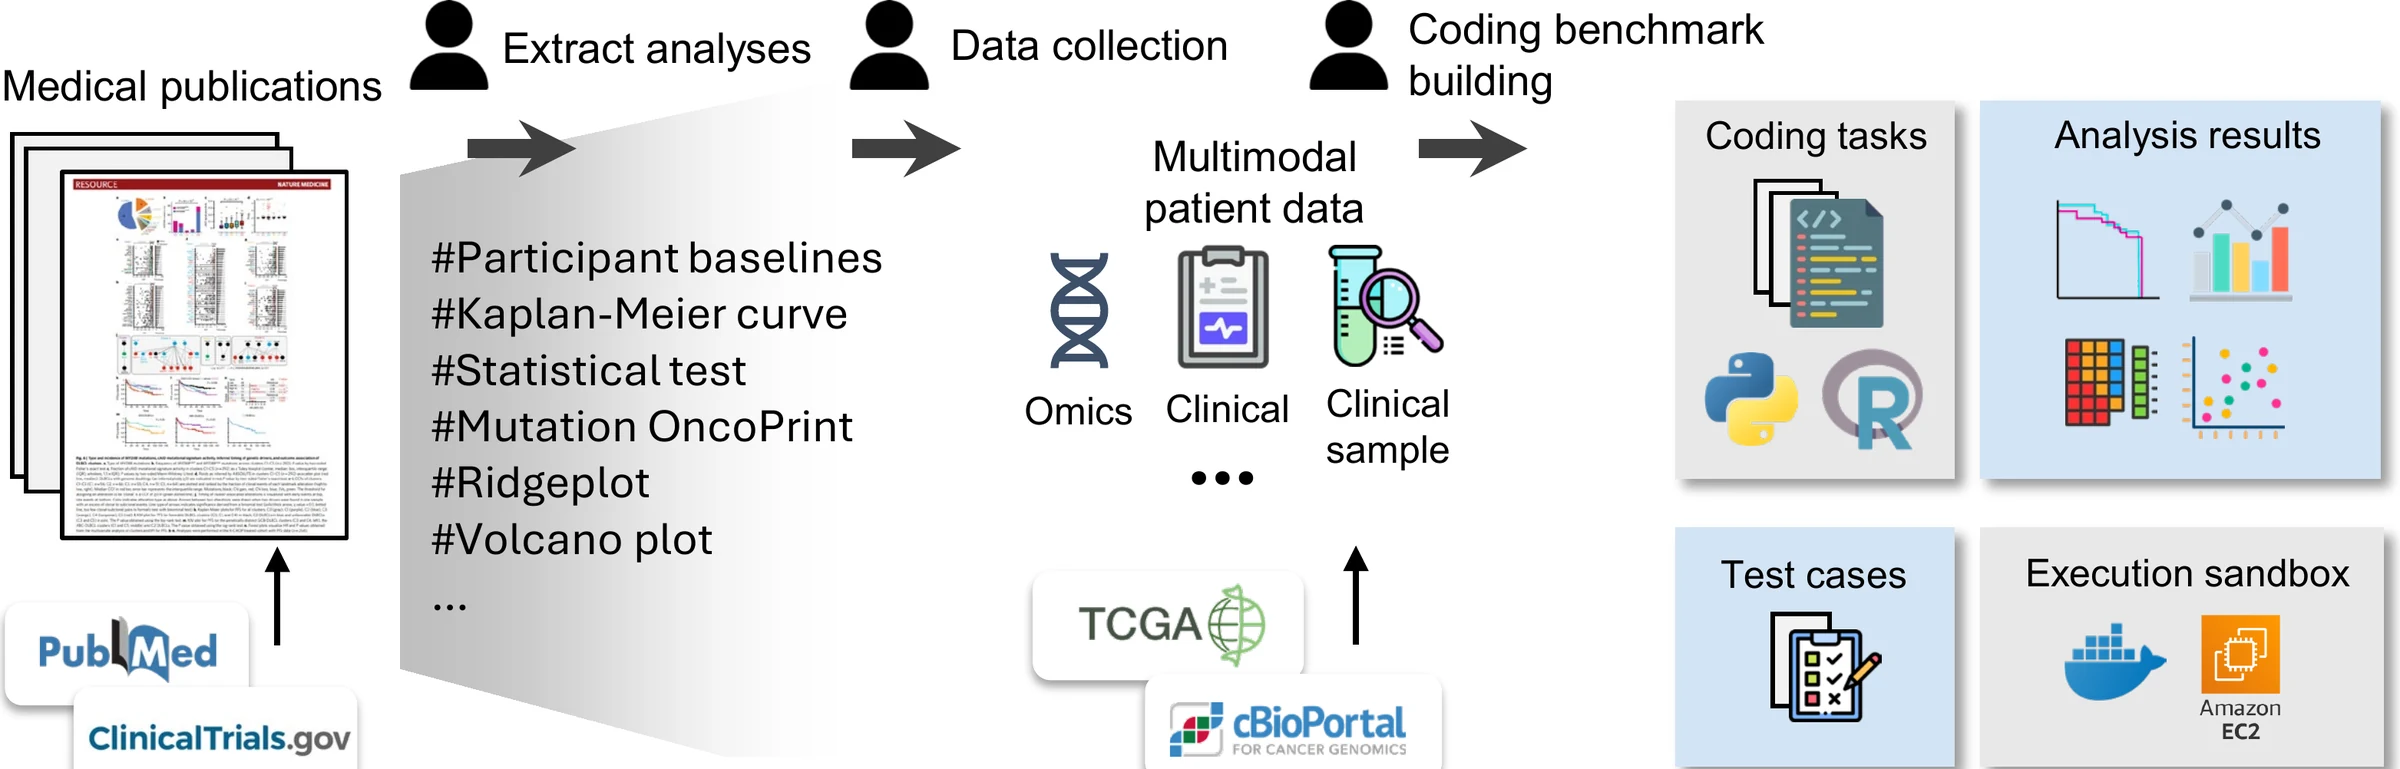
To find out, the study built BioDSBench: 293 coding tasks in Python and R, derived from 39 published studies across seven research areas from biomarkers to pan-cancer analysis, each run on real patient data and checked with test cases. Eight proprietary and eight open-source LLMs reached an overall accuracy below 40%.
The most effective fix was to plan first. An agent that drafts an analysis plan, checks it against the actual data and refines it before writing code reached 74%. The same idea drives a platform where researchers develop analysis plans together with an LLM and run them in one environment.
Benchmark the models, find what helps, then build it into a tool.
Turn published analyses into coding tasks with reference answers and test cases, and score each model by whether its code passes them on the first attempt.
Compare adaptation strategies, including few-shot examples, retrieval, automatic prompting, self-reflection, code agents and plan-first prompting, across easy, medium and hard tasks.
Put plan-first co-development into a platform where users make requests, review generated code and run it on selected datasets, then test it with medical researchers.
Headline numbers
All three numbers are from the published abstract. Accuracy is the share of tasks whose generated code passes the test cases.
| Strategy | Easy | Medium | Hard |
|---|---|---|---|
| Few-shot | 60% | 32% | 13% |
| AutoPrompt | 50% | 34% | 3% |
| RAG | 60% | 37% | 10% |
| ManualPrompt | 63% | 45% | 13% |
| CodeAgent | 50% | 13% | 13% |
| PlanPrompt | 63% | 58% | 48% |
| DSWizard (plan-first agent) | 90% | 76% | 55% |
Making Large Language Models Reliable Data Science Programming Copilots for Biomedical Research