About the Paper
Benchmarking 16 LLMs on 293 coding tasks from 39 biomedical studies shows overall accuracy below 40%; an agent that first drafts and iteratively refines an analysis plan reaches 74%.
Making Large Language Models Reliable Data Science Programming Copilots for Biomedical Research
Co-authored paper on making LLMs reliable data-science programming copilots published in Nature Biomedical Engineering.
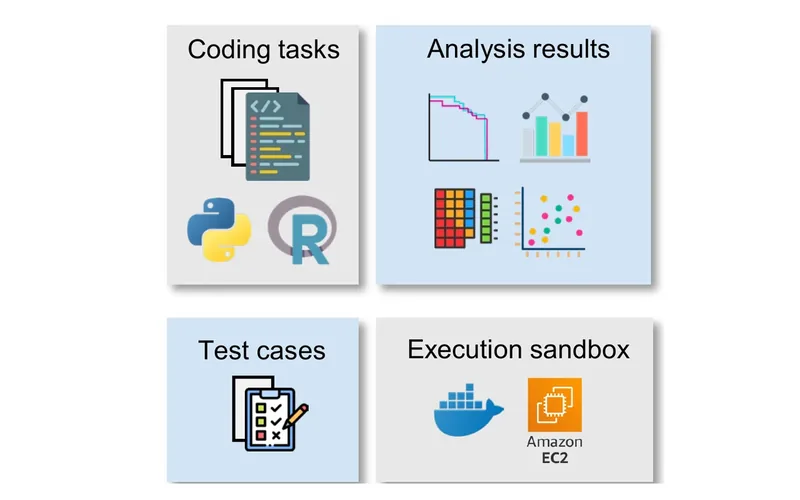
Benchmarking 16 LLMs on 293 coding tasks from 39 biomedical studies shows overall accuracy below 40%; an agent that first drafts and iteratively refines an analysis plan reaches 74%.